Google's Gemini 4 Argon Lands Days After GPT-6.1 Terra—Pick Wrong and Pay
Google shipped Gemini 4 Argon right after OpenAI's GPT-6.1 Terra. Two frontier models, one week. Builders now have to re-run evals before committing to either.
Two Frontier Releases in One Week
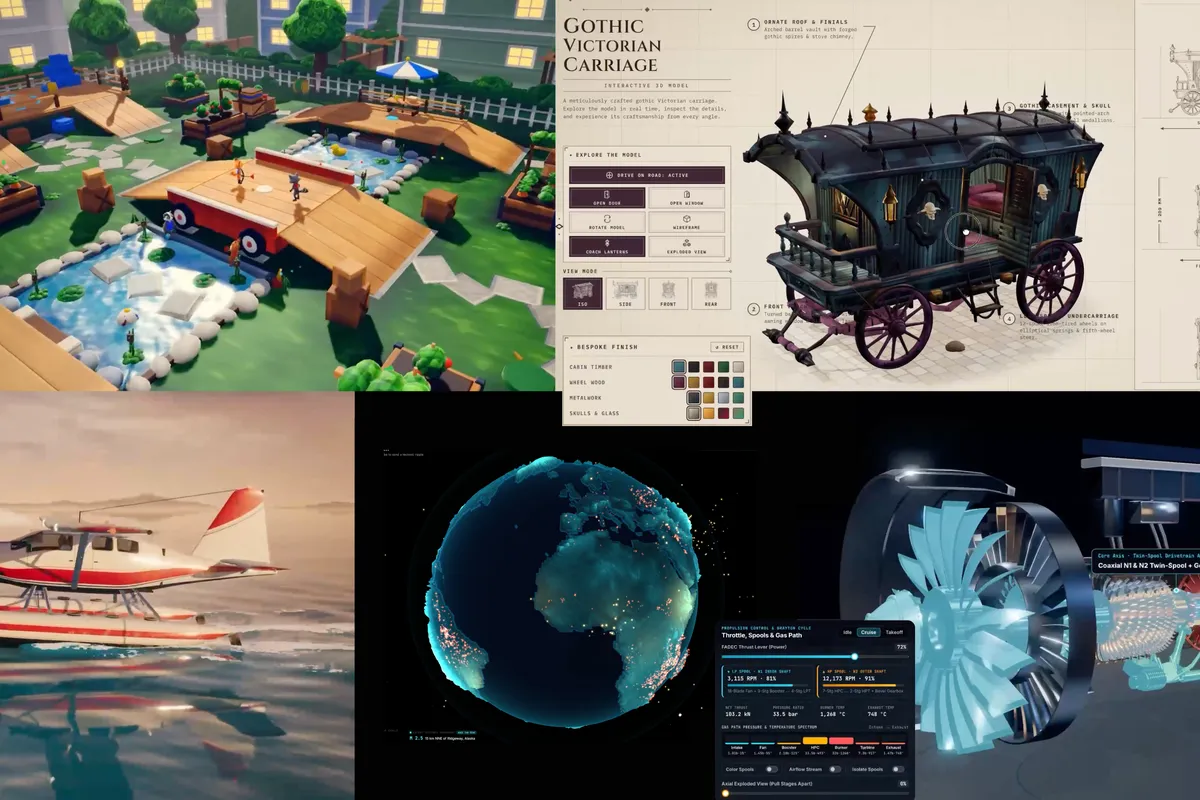
Google introduced Gemini 4 Argon, framing it around solving harder problems. It lands in the same window as OpenAI’s GPT-6.1 Terra, which means this is the week builders have to reassess model selection rather than coast on last quarter’s benchmark table.
The timing is the story. Back-to-back frontier releases from Google and OpenAI compress the decision window: you can no longer assume the model you wired into production three months ago is the frontier default. Argon is the newer entrant in this pair, but “newer” is not a benchmark.
There is a second-order effect worth naming. When two labs ship inside the same week, the comparison set changes faster than most teams can run a proper evaluation. Procurement cycles, security reviews, and internal sign-off all move on a slower clock than release notes. The result is a widening gap between what is available and what is actually validated inside your organization—and that gap is where bad defaults get locked in. The team that ships a model choice on announcement day and the team that ships it three weeks later on evidence are making different bets, and only one of them is reversible cheaply.
That asymmetry deserves to be spelled out, because it is easy to mistake speed for rigor. The announcement-day team gets the headline capability first, but it also absorbs the unknown failure modes in front of its own users, with no baseline to compare against and no accumulated evidence to fall back on. The evidence team looks slow on the roadmap and fast in the incident channel, because by the time it commits, it already knows how the model behaves on the prompts that matter. Neither posture is free. The question is which cost you would rather pay: a visible delay now, or an invisible regression later that surfaces as a support ticket you cannot reproduce.
What Argon Actually Claims
Google’s announcement positions Argon on harder problem-solving, not on being the cheapest or the fastest. That framing matters because the previous wave of releases competed on price-per-token and latency; a model pitched at difficulty shifts the eval question from “can it answer” to “can it hold a long, multi-step task without collapsing.”
If you are running agent workloads, that is the axis you should test. A model that is marginally better on a single-turn benchmark but degrades across twenty tool calls is worse for production than a model that is boring on trivia and stable on chains.
The mechanism behind that degradation is worth understanding, because it tells you what to measure. Long-horizon tasks compound error: each step inherits the state left by the previous one, so a small per-step failure rate multiplies rather than adds. A model can look strong on isolated prompts and still fall apart when it has to carry context, recover from a tool error, and stay inside a schema across a sequence. That is why per-step scoring beats per-response scoring—it exposes the compounding instead of hiding it behind a single pass/fail. It also explains why vendor framing around “harder problems” is a claim about depth, not breadth, and depth is exactly what a short benchmark cannot see.
Consider what compounding looks like in arithmetic. A model that succeeds on 95 percent of individual steps sounds excellent until you chain twenty of them: the odds of a clean end-to-end run fall well below the per-step figure, and every additional tool call widens the gap. The practical implication is that a small edge on a hard-reasoning chart can evaporate entirely once the task gets long, while a model that looks unremarkable on isolated prompts can win on the chain because it does not drift. That is the distinction the “harder problems” framing points at, and it is the one your eval has to reproduce if you want the claim to mean anything for your product.
Terra Is the Comparison You Cannot Skip
GPT-6.1 Terra arrived first in this window, and OpenAI’s own release framing already set expectations for the next tier. Running Argon against Terra is now the minimum viable eval, not an optional one. The trap is comparing vendor-published numbers instead of your own task suite.
Builders who skip this step end up with a model-selection decision made by marketing. The fix is unglamorous: take the twenty prompts that actually break your system, run both models, and score pass/fail per step rather than per response.
There is counter-evidence to hold alongside the hype, though. Back-to-back releases do not guarantee that either model is better for your workload. Frontier gains often concentrate in the task categories the labs optimized for, and a model that tops a hard-reasoning chart can regress on the narrow, well-specified tasks a production pipeline depends on. The honest position is that a new release resets the question, not the answer. Treat the announcement as a reason to re-run your suite, not as evidence that the suite will pass.
This is not a counsel of cynicism; it is a counsel of measurement. The labs are optimizing against their own eval sets, and those sets are necessarily broader and more public than yours. A gain that shows up on a shared benchmark can coexist with a loss on the specific distribution your users generate—unusual input formats, domain jargon, legacy edge cases that no public suite has ever seen. The only way to know which side of that line you are on is to run the prompts you already know are hard, and to run them the same way twice so the comparison is honest.
The Reassessment Checklist
Before you swap a production model for Argon or Terra, three things need to move together: your eval suite, your cost model, and your fallback path. A frontier upgrade that doubles token spend on retries is a downgrade in disguise.
The cost model deserves its own line because it is the easiest to get wrong. Retries, longer reasoning traces, and more tool calls all show up as spend that a per-token price sheet does not capture. Model the fully loaded cost of a failed task—the tokens burned before the failure, the retry, and the human time to notice—and the cheapest-looking option often stops looking cheap.
Also check structured output reliability. If your pipeline depends on JSON that survives validation, test that specifically—frontier models are not automatically better at schema adherence, and a model that solves harder problems can still emit a malformed object under pressure.
The fallback path is the third leg, and it is the one teams skip under deadline pressure. If the new model degrades in production, what routes the traffic back? A pinned previous version, a feature flag, or a router that can switch per-request all count—but only if they are tested before you need them. A migration without a rehearsed rollback is not a migration; it is a hope.
Each of these three legs fails in a characteristic way when it is neglected. A stale eval suite gives you confidence you did not earn. A naive cost model gives you a budget that survives the demo and not the month. An untested fallback gives you a plan that exists on paper and nowhere else. The point of moving them together is that they constrain each other: a cost model built on your real retry behavior will change which model your eval should even be testing, and a rehearsed rollback changes how aggressively you can afford to try the new one.
What to Do This Week
Do not migrate on the announcement. Migrate on your own numbers. Pick the hardest task in your product, run Argon and Terra side by side, and compare failure modes rather than averages.
Failure-mode comparison is the part most eval write-ups skip. Averages tell you which model wins on paper; failure modes tell you which one fails in a way you can tolerate. A model that fails loudly and early is recoverable. A model that fails quietly—plausible output, wrong content, valid-looking JSON with a missing field—is the one that costs you a weekend. Score the shape of the failure, not just its frequency.
The builders who win this week are the ones who treat back-to-back frontier releases as a forcing function for eval hygiene, not as a reason to rewrite their stack. The models will keep arriving on this cadence. The teams that build a repeatable way to test them—same prompts, same scoring, same rollback—will make each future release a routine decision instead of a scramble. That is the durable advantage, and it does not depend on which lab shipped last.
For the individual reader, that reframes what this week actually asks of you. It is not a demand to pick a winner between Argon and Terra; it is a demand to know, in concrete terms, how your system fails and which failure shapes you can absorb. The teams that can answer that question quickly will treat every future release as a cheap experiment. The teams that cannot will keep paying for the same lesson, one announcement at a time.
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Control Room Can Halt Research Output in 35 Seconds—What Keeps Running?
OpenAI's Control Room puts research inference behind a central stop system. For builders, the hard question is what a stopped workload can keep doing.
OpenAI's Control Room Can Cut Off Research—What Does It Leave Running?
OpenAI's Control Room puts research inference behind a central permission check. For builders, the revealing detail is what a stop command leaves running.
Fable 5.2 and Mythos 5.2 Share a Core—So What Are You Choosing?
Anthropic's Fable 5.2 and Mythos 5.2 share an underlying system but different safeguards. For builders, the first decision is access, then the acceptance test.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Decisions API Scores 1,000 Questions—Can Its Confidence Travel?
- Edge0-145B Promises Frontier AI on Your PC—Which PC?
- Hydrogen Starts at $1.50—What Will a Finished Task Really Cost?
- $0.10 per Million Tokens: Decisions API Has a Different Catch
- Control Room Can Halt Research Output in 35 Seconds—What Keeps Running?
- Huawei Released MACaQ—Will Its Quantizer Fit Your Local Stack?
Tags
> Stay in the loop
Weekly AI tools & insights.