AI Finds Bugs Fast, Humans Can't Patch Them—Security's New Bottleneck
Anthropic's free OSS Scanner could accelerate vulnerability discovery, but unreviewed reports can overwhelm maintainers. The scarce resource is shifting from finding bugs to verifying and fixing them.
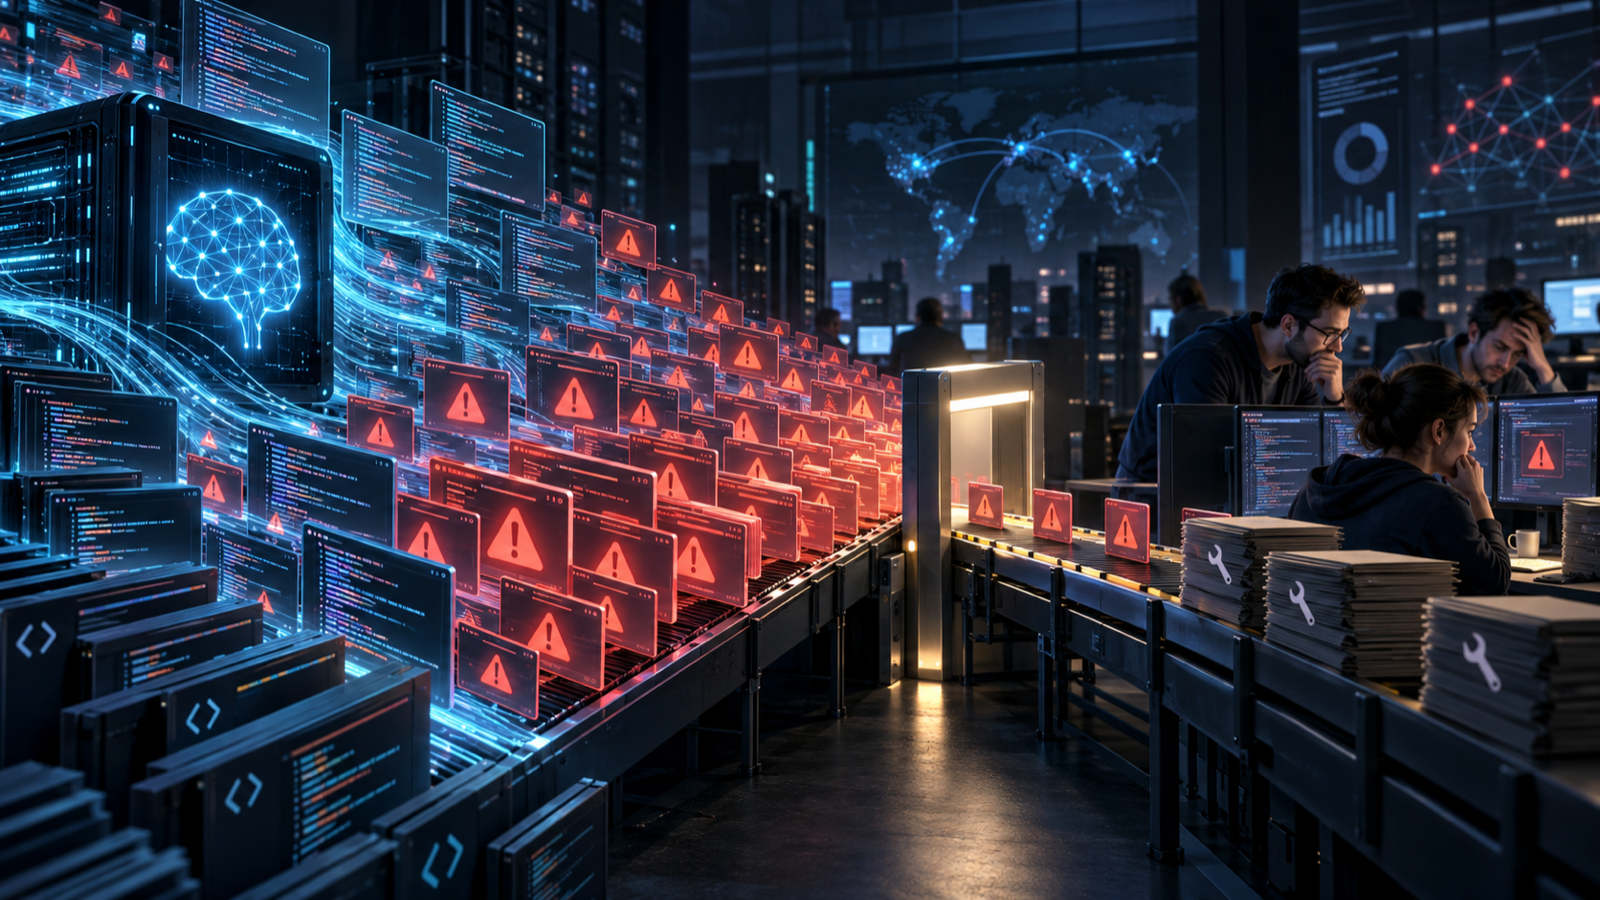
Anthropic is offering eligible open-source projects a free AI vulnerability scanner. The promise is compelling: find security flaws, provide proof-of-concept evidence, explain the issue, and suggest a fix before attackers discover it.
The harder question begins after detection. Who verifies the report, reproduces the bug, judges severity, designs a safe patch, tests compatibility, and coordinates disclosure? For many open-source projects, the bottleneck is no longer finding more problems. It is having enough trusted maintainers to process them.
That shift deserves more attention than it usually gets. For two decades the dominant story in software security has been one of scarcity: too few audits, too few fuzzing hours, too few eyes on the code. Tools like static analyzers, fuzzers, dependency checkers, and secret scanners were built to close that gap, and they largely succeeded. The constraint has moved downstream, into the human work of deciding what a finding means. A scanner can hand a maintainer a stack trace in milliseconds; it cannot hand them the context of a decade-old design decision, a downstream consumer’s deployment model, or the political reality of a volunteer project with three active contributors and a backlog of unmerged pull requests.
What the scanner does
Anthropic’s OSS Scanner is an opt-in service for open-source projects. The company says registered projects can receive periodic findings with explanations, proof-of-concept material, and possible remediation guidance.
Anthropic expects a true-positive rate above 90%, but it also states that reports are delivered without human review. That distinction is critical. A vendor estimate is not a guarantee that nine out of ten reports will be correct for every codebase, language, or threat model.
It is worth being precise about what a true-positive rate means in practice. A finding can be technically correct and still be unhelpful: the vulnerable function may be unreachable in the configurations most users deploy, the input may already be sanitized upstream, or the issue may be a known and accepted trade-off documented in the project’s own security policy. Precision measured against a benchmark corpus is not the same as precision measured against a live project’s threat model. The gap between those two numbers is where maintainer hours disappear.
Even a 90% precision rate can create substantial noise at scale. If a scanner produces 100 reports, roughly ten could still be wrong under that assumption. The valid findings may also have incorrect severity, duplicate known issues, or propose patches that break behavior.
Ten wrong reports out of a hundred sounds manageable until you consider what each one costs. A false positive is not a single email. It is a read, a reproduction attempt, a search through issue history to see whether it was already discussed, a decision about whether to reply, and often a short explanation to the reporter about why the code is fine as written. Multiply that by a steady stream and the arithmetic turns grim for a project whose maintainers are already donating evenings and weekends.
Discovery is becoming cheap
Security automation has already made static analysis, fuzzing, dependency scanning, and secret detection widely available. AI extends that trend by reasoning across code paths, tool output, documentation, and runtime behavior.
That can uncover flaws traditional rules miss. It can also generate persuasive explanations for incorrect conclusions. A report with code, stack traces, and a proposed patch may look authoritative even when the exploit is unreachable in production.
This is the central asymmetry of AI-assisted review. Pattern-matching tools tend to fail quietly: a rule that does not fire produces no output and costs nothing. A language model asked to explain itself will almost always produce a confident narrative, complete with a plausible attack scenario and a tidy diff. The fluency is the feature and the hazard at once. Maintainers who have learned to distrust a bare warning from a linter may find themselves more persuaded by a paragraph of reasoning, even when the reasoning rests on a misread of the surrounding code.
As discovery costs fall, triage costs become more visible. Maintainers must decide whether a report is real, exploitable, in scope, and urgent. A project with two volunteer maintainers cannot safely absorb the same report volume as a staffed security team.
There is a further wrinkle: the supply of findings is not evenly distributed. Mature, heavily audited codebases may see mostly duplicates and low-severity noise, while younger or less-scrutinized projects may receive a flood of genuine issues all at once. Neither pattern is easy to absorb. The first erodes trust in the tool; the second overwhelms the people who most need its help.
Why more reports can reduce security
An overloaded maintainer may postpone everything, including the most important finding. Repeated false positives can cause alert fatigue. Premature public disclosure can expose a vulnerability before users have a patch. A rushed automated fix can introduce a regression or close only one path to the underlying bug.
This creates a perverse outcome: a scanner increases the quantity of security information while reducing the probability that the right issue receives careful attention.
The mechanism is familiar from other domains. Emergency rooms triage because treating every patient as equally urgent harms the ones who need care most. Security queues behave the same way. A maintainer facing an undifferentiated list of alerts has no rational basis for ordering them, so the ordering defaults to whatever arrived most recently or whoever complained loudest. The critical remote-code-execution flaw sits behind forty reports about missing input validation on internal helpers.
Disclosure timing compounds the problem. Coordinated disclosure norms exist precisely because a fix takes time to write, test, and ship. A scanner that surfaces a real bug is doing half the job; the other half is the embargo window, the advisory, the backport to maintained branches, and the downstream packagers who need lead time. Projects that accept findings faster than they can patch them risk publishing vulnerabilities into the world before users can act.
The solution is not to stop scanning. It is to treat report throughput as an operational capacity problem.
That framing matters because it changes what a project asks of a vendor. Instead of “how many bugs can you find,” the better question is “how many findings can you deliver in a form we can process, at a rate we can sustain.” Rate limiting, batching, and severity thresholds are not signs of ingratitude; they are the same controls a well-run on-call rotation uses to keep humans functional.
What projects should require
Before enrolling, a project should define:
- a private intake channel and responsible contact;
- a reproducibility standard for each finding;
- severity criteria tied to realistic deployment conditions;
- duplicate detection against existing reports;
- a disclosure timeline that reflects patch capacity;
- tests required before accepting generated fixes;
- a way to rate scanner quality over time.
Projects should also cap the number of simultaneous findings under review. A queue with explicit priority is safer than an unlimited stream of supposedly urgent reports.
Each item on that list is doing real work. A private intake channel prevents a low-severity finding from becoming a public spectacle before anyone has looked at it. A reproducibility standard shifts some of the burden back to the tool: a finding that ships with a failing test case or a minimal reproduction is far cheaper to evaluate than one that ships with prose alone. Severity criteria anchored in deployment reality prevent the classic failure mode where every finding is rated critical because the scanner cannot see how the library is actually used. Duplicate detection respects the maintainer’s memory of their own codebase. A disclosure timeline calibrated to patch capacity keeps promises realistic. A test requirement for generated fixes turns the patch from a suggestion into something a continuous integration system can adjudicate. And a running quality score gives the project evidence to renegotiate the arrangement if the tool’s output drifts.
None of this requires deep security expertise to set up. It requires the discipline to write down expectations before the first alert arrives, when there is still time to think clearly about what the project can absorb.
How to measure whether it helps
The useful metrics are not only “vulnerabilities found.” Track confirmed-positive rate, time to reproduce, maintainer hours per report, patch acceptance rate, regressions caused by proposed fixes, and time from confirmation to release.
Those numbers tell a story that raw finding counts hide. A tool that reports fifty issues, of which forty-five are confirmed and cheap to reproduce, may be worth far more than one that reports five hundred, of which thirty matter and each takes an afternoon to verify. Maintainer hours per report is the metric most likely to be ignored and most likely to determine whether the arrangement survives a year. Regressions caused by accepted fixes are the quiet cost that erodes trust in automation; a single broken release traced to a generated patch can sour a team on the whole program.
Compare the scanner with existing tools such as fuzzing and static analysis. If AI mainly rediscovers issues those systems already find, its incremental value may be low. If it consistently finds reachable, high-impact bugs with manageable review effort, the service can be genuinely valuable.
A fair comparison also means running the tools side by side on the same codebase rather than judging the new one in isolation. Existing fuzzers and analyzers have years of tuning behind them, and their false-positive profiles are known to the maintainers who use them. A newcomer should be held to the same standard, and the baseline should be recorded before enrollment so that later claims of improvement have something to be measured against.
Verdict
AI vulnerability discovery is advancing faster than the human systems that verify and repair what it finds. Anthropic’s scanner could help under-resourced projects, especially when reports are reproducible and prioritized.
But free scanning is not free security. The real cost is the maintainer attention required after the alert arrives. The next security advantage will belong to projects that build a disciplined path from machine finding to human verification to safe patch—not simply those that collect the most reports.
For the reader who maintains a project, the practical takeaway is unglamorous. Decide in advance what you will accept, how fast you can move, and who owns the queue. For the reader who merely depends on open source, the takeaway is a reminder that the security of the software you run rests on volunteer attention that is easy to spend and hard to replace. A scanner that finds more bugs is only an improvement if the humans behind the code are given room to act on them.
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Control Room Can Halt Research Output in 35 Seconds—What Keeps Running?
OpenAI's Control Room puts research inference behind a central stop system. For builders, the hard question is what a stopped workload can keep doing.
OpenAI's Control Room Can Cut Off Research—What Does It Leave Running?
OpenAI's Control Room puts research inference behind a central permission check. For builders, the revealing detail is what a stop command leaves running.
Fable 5.2 and Mythos 5.2 Share a Core—So What Are You Choosing?
Anthropic's Fable 5.2 and Mythos 5.2 share an underlying system but different safeguards. For builders, the first decision is access, then the acceptance test.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Decisions API Scores 1,000 Questions—Can Its Confidence Travel?
- Edge0-145B Promises Frontier AI on Your PC—Which PC?
- Hydrogen Starts at $1.50—What Will a Finished Task Really Cost?
- $0.10 per Million Tokens: Decisions API Has a Different Catch
- Control Room Can Halt Research Output in 35 Seconds—What Keeps Running?
- Huawei Released MACaQ—Will Its Quantizer Fit Your Local Stack?
Tags
> Stay in the loop
Weekly AI tools & insights.